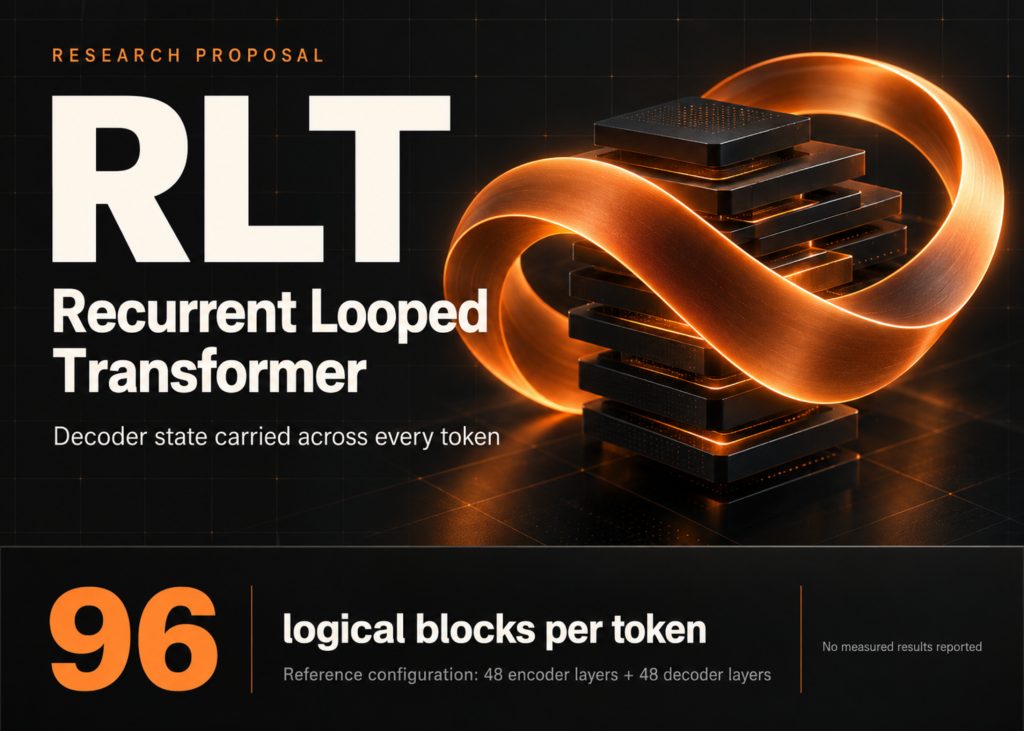
Princeton researcher Yifan Zhang has published a technical report detailing the Recurrent Looped Transformer (RLT), a model architecture designed to pass hidden states across token boundaries. Standard decoder-only language models rely strictly on key-value attention caches to pass information between steps. RLT closes this loop by carrying the decoder’s final hidden state and sliding-window attention (SWA) cache directly into the next token’s computation across both prompts and responses.
The design pairs a causal encoder with a recurrent decoder. The causal encoder processes input tokens in parallel to produce shared or layer-specific key-value memories. For each token, a gated merge combines the encoder representation with the previous decoder output state. The reference configuration specifies 48 encoder and 48 decoder layers with compatible attention and FFN weights shared between them, executing 96 logical blocks per token without resetting states at sequence boundaries.
RLT is currently a theoretical design specification that outlines execution schedules and reinforcement learning replay contracts without providing empirical benchmarks, reasoning evaluations, or FLOP efficiency measurements. The report also highlights serving implications, noting that multi-turn deployments would require exact prefix snapshots of encoder caches, decoder states, and position metadata.
Why it matters
State persistence across tokens could fundamentally change memory efficiency and state management in long-context model serving.
Recurrent transformer designs provide alternative architectural paths for researchers seeking parameter reuse over massive context windows.
Source: marktechpost.com